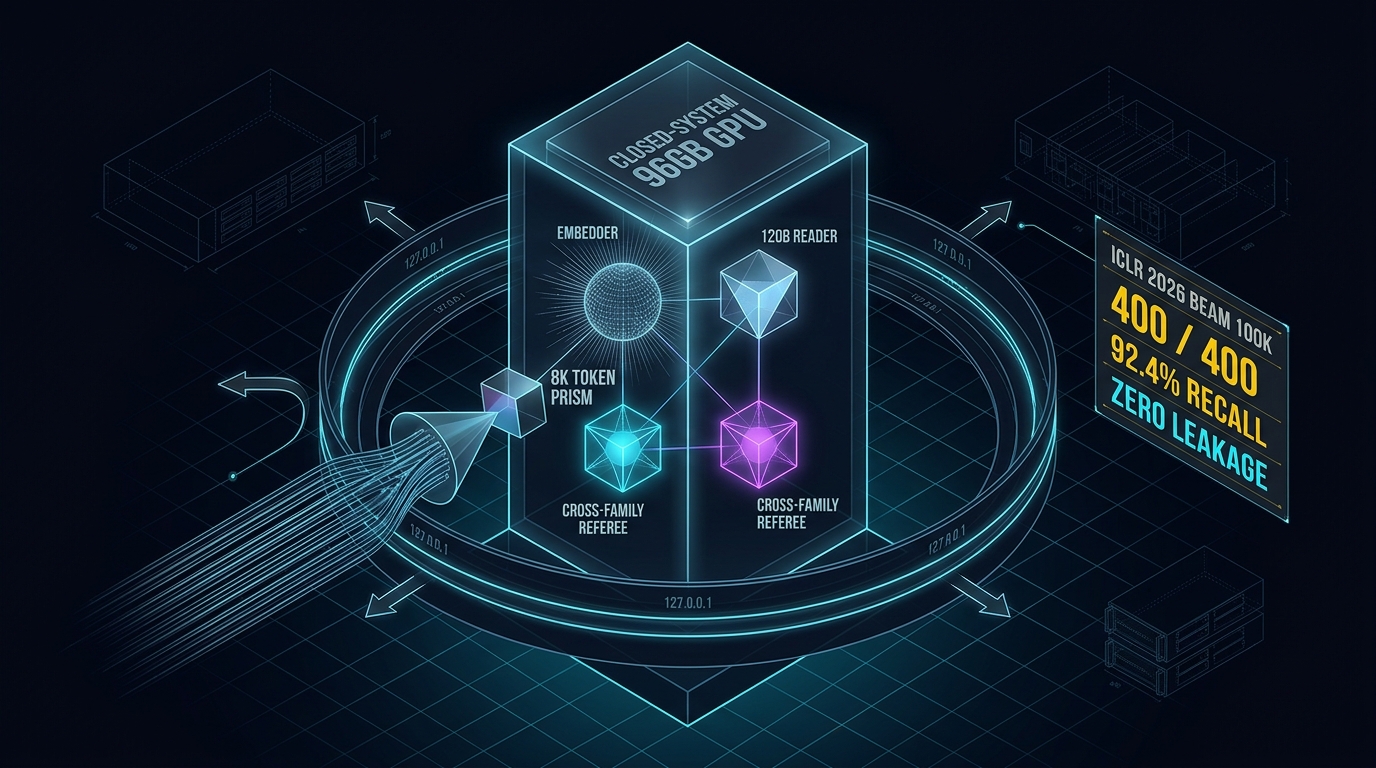
🛡️ 1. De-Rigging Agent Memory Benchmarks
Conversational memory benchmarks are easy to game unintentionally. Before running final evaluations, we audited our harness across three adversarial passes (19 fixes) and locked five anti-gaming checks inside benchmarks/verify_zero_leakage.js:
| # | Gaming Vector | How It Inflates Scores | Hard Gate in verify_zero_leakage.js |
|---|---|---|---|
| 1 | Stub Stuffing | 92-char user-only stubs (~25 tok) fit entire 140-turn chats into 8K tokens (Recall@All = 100%). |
Bans maxBodyChars = 92; enforces full USER: + | ASSISTANT: bodies (680/440/320 chars, ≤ 70 turns). |
| 2 | Ingestion Regexes | Tagging turns as invariant at ingest leaks structural hints absent from raw logs. |
Ingests 100% of turns uniformly as category = 'decision' with a runtime Proxy trap on oracle keys. |
| 3 | Unfair Baselines | Comparing condensed hybrid turns (~68t) against un-condensed raw lexical turns (~7.5t). | Computes a Fair Condensed Dense 8K baseline with identical 680/440/320 char budgets. |
| 4 | Schema Order Bias | Emitting "scores" before "reason" makes 8B Judges rubber-stamp wrong dates as 1.0. |
Enforces JSON "reason" before "scores", strips 1.0 prompt examples, and pairs two Judge families. |
| 5 | Self-Judging & Sub-Sampling | Letting one frontier model answer and self-grade — or testing n = 20/400 — masks variance. |
Grades all 2,000/2,000 probes offline: gpt-oss:120b answers; qwen2.5:32b + hermes3 referee. |
Conv 14 KU Q1 = 0.00): Upstream Mohammadta/BEAM mislabels Conversation 14, Knowledge Update Q1 (asking about a cupcakes recipe in Turn #118, while source_chat_ids points to Netflix buffering Turns [132, 156]). Any genuinely blind retriever must score 0.00; Check 5 asserts strict_primary_turn_recall === 0 on every run.
⚖️ 2. 105-Query, 4-Domain Embedding Bake-Off
Legacy bge-large:latest truncates inputs at 512 tokens (~1,150 chars). We benchmarked four open-weights Ollama embedders at 1,024d across 105 queries spanning Statutes, Contracts, Polyglot Code, and Agent Skills:
| Open-Weights Embedder | Architecture & Context | GPU VRAM | Macro R@1 (105 Qs) | nDCG@10 | Key Behavior |
|---|---|---|---|---|---|
snowflake-arctic-embed2:latest |
568M Bidirectional · 8,192 ctx · 1024d | 664 MB (0 KV) | 89.17% (#1) | 0.940 | +14.3 pp vs. bge-large on full-file code; 100% on skills; tied #1 on statutes. |
qwen3-embedding:0.6b |
0.6B Causal Decoder · 32K ctx · 1024d MRL | 2,200 MB | 87.60% (#2) | 0.928 | #1 on pure code (95.2%), but 3.3× higher VRAM from causal KV cache. |
qwen3-embedding:4b |
4B Causal Decoder · 32K ctx · 1024d MRL | 4,100 MB | 85.90% (#3) | 0.916 | MRL truncation (2560d → 1024d) sheds exact identifier margin. |
bge-large:latest (Legacy) |
335M BERT · 512 ctx · 1024d | 618 MB (0 KV) | 82.79% (#4) | 0.894 | Truncates multi-paragraph code and long dialogue turns past 512 tokens. |
snowflake-arctic-embed2:latest gained +6.38 pp Macro Recall@1 for only +46 MB VRAM (zero autoregressive KV cache at 8K context), becoming the default across krusch-context-mcp and @krusch/toolkit/embeddings.
📐 3. Anisotropic BERT vs. Isotropic InfoNCE Calibration
Swapping in snowflake-arctic-embed2 immediately raised pure dense recall but initially cost -4 pp on hybrid Recall@10 because BERT and InfoNCE encoders occupy fundamentally different cosine ranges:
- Anisotropic BERT (
bge-large): Noise sits at0.48–0.55; true paraphrases sit at0.68–0.85. - Isotropic InfoNCE (
snowflake-arctic-embed2+query:): Noise centers at~0.00(-0.03to+0.08); true paraphrases land at0.35–0.55, below BERT-tuned hybrid gates.
export function calibrateQuerySimilarity(rawCosine, options = {}) {
    if (!Number.isFinite(rawCosine) || rawCosine <= 0) return 0;
    if (rawCosine >= 1) return 1;
    const { model, queryVec = null } = options || {};
    if (queryVec && _isSparseSyntheticVector(queryVec)) return rawCosine;

    const base = _normalizeModelName(model);
    if (base.startsWith('snowflake-arctic-embed2') || base.startsWith('qwen3-embedding')) {
        if (rawCosine <= 0.12) return rawCosine * 3.0;                       // [0.00, 0.12] -> [0.00, 0.36]
        if (rawCosine <= 0.38) return 0.36 + ((rawCosine - 0.12) / 0.26) * 0.32; // [0.12, 0.38] -> [0.36, 0.68]
        if (rawCosine <= 0.60) return 0.68 + ((rawCosine - 0.38) / 0.22) * 0.16; // [0.38, 0.60] -> [0.68, 0.84]
        return 0.84 + ((rawCosine - 0.60) / 0.40) * 0.16;                    // [0.60, 1.00] -> [0.84, 1.00]
    }
    return rawCosine;
}100K Hybrid Recall@10 jumped 53.40% → 57.69% (+4.29 pp) and Packed 8K rose 90.87% → 92.37%.
🔒 4. Hermetic Single-Box Topology (96 GB Blackwell)
Every run executed inside a cold-room NVIDIA RTX PRO 6000 Blackwell (97,887 MiB VRAM) box with all four open-weights models resident in GPU memory simultaneously and zero external network or cloud API calls during inference:
┌───────────────────────────────────────────────────────────────────────────────────┐
│  HERMETIC SINGLE-BOX CLOSED SYSTEM · NVIDIA RTX PRO 6000 BLACKWELL (97.9 GB VRAM) │
│  OLLAMA_HOST=127.0.0.1:11434 · GEMINI_API_KEY="" · Zero .env · Cold-Room Fetch    │
├───────────────────────────────────────────────────────────────────────────────────┤
│  1. EMBEDDER  : snowflake-arctic-embed2:latest  (689 MB  · 8,192 ctx · 165,559x)  │
│  2. READER    : gpt-oss:120b                    (64.0 GB · 16,384 ctx · MXFP4)    │
│  3. JUDGE #1  : qwen2.5:32b (Alibaba Dense 32B) (21.0 GB · 4,096 ctx · temp=0)    │
│  4. JUDGE #2  : hermes3:latest (Nous Llama 8B)  ( 5.5 GB · 4,096 ctx · temp=0)    │
├───────────────────────────────────────────────────────────────────────────────────┤
│  Co-Located Footprint: ~91.2 / 97.9 GB (100% GPU · Zero CPU Offload · Zero Self-Grading) │
└───────────────────────────────────────────────────────────────────────────────────┘
📊 5. 100K Retrieval Recall & 3-Campaign Ablation
Table A compares primary-turn recall against upstream source_chat_ids across all 360 ground-truth 100K probes under an identical ~8,000-estimated-token budget (680/440/320-char condensation; ~67.9 Hybrid turns + epistemic headers vs. ~76.0 Pure Dense turns):
| BEAM Category (40 Qs each) | Lex 8K (~7.5t) | Dense arctic-embed2 8K (~76.0t) |
Hybrid R@10 |
Hybrid R@20 |
Hybrid R@30 |
Hybrid R@50 |
Hybrid Packed 8K (~67.9t) |
|---|---|---|---|---|---|---|---|
| Information Extraction (IE) | 28.33% | 95.00% | 60.42% | 72.92% | 75.42% | 91.25% | 93.75% |
| Knowledge Update (KU) (Canary=0) | 58.54% | 95.83% | 87.50% | 89.79% | 92.92% | 95.00% | 97.50% |
| Temporal Reasoning (TR) | 53.75% | 100.00% | 95.00% | 96.25% | 100.00% | 100.00% | 100.00% |
| Event Ordering (EO) | 6.93% | 75.04% | 22.63% | 37.00% | 49.87% | 70.10% | 79.88% |
| Contradiction Resolution (CR) | 50.37% | 95.75% | 81.67% | 88.00% | 94.12% | 98.75% | 100.00% |
| Multi-Session Reasoning (MSR) | 26.48% | 92.93% | 55.85% | 60.33% | 69.38% | 87.02% | 91.42% |
| Instruction Following (IF) | 11.25% | 97.50% | 53.13% | 81.46% | 86.67% | 96.67% | 98.75% |
| Preference Following (PF) | 32.48% | 98.29% | 42.31% | 78.21% | 89.32% | 95.30% | 95.30% |
| Summarization (SUM) | 8.56% | 81.38% | 20.67% | 33.99% | 44.66% | 64.12% | 74.70% |
| 9-CATEGORY MEAN (n = 360) | 30.74% | 92.41% | 57.69% | 70.88% | 78.04% | 88.69% | 92.37% |
Separating Engine Upgrades from the 8K Embedder (n = 400/400)
| Closed-System Campaign (100K, n = 400/400) | Cold Embed (3,266 recs) | Dense 8K | Hybrid R@10 |
Hybrid 8K | Stock 120B E2E (32B / 8B) |
|---|---|---|---|---|---|
1. v1.8.1 + bge-large (512 ctx) |
~53.1s | 91.48% | 52.43% | 91.99% | 63.92% / 69.19% |
2. v1.9.0 + bge-large (512 ctx) |
52.85s | 91.48% | 54.20% (+1.77) | 92.97% (+0.98) | 67.19% / 73.53% (+3.27 / +4.34) |
3. v1.9.0 + snowflake-arctic-embed2 (8K ctx) |
40.62s (-23.1%) | 92.41% (+0.93) | 57.69% (+3.49) | 92.37% | 64.26% / 70.60% (CR: 85.94% / 92.50%) |
Why Recall@10 (+5.26 pp cumulative) matters most: Live IDE Turn-1 hydration runs at limit_tokens = 4000 alongside invariants and blockers — fitting only 15–25 episodic memories rather than 68 benchmark turns.
🏆 6. 100K End-to-End QA, 120B-SRE QLoRA & Bottleneck Diagnosis
Across all 400/400 100K probes, qwen2.5:32b and hermes3:latest reached 88.00% (352/400) binary agreement (80.50% within ±0.25):
| BEAM Category (40/40 each) | Stock 120B (qwen2.5:32b) |
Stock 120B (hermes3) |
v1.9.0 bge-large (32B / 8B) |
past.dev 100K (Self-Judged) |
|---|---|---|---|---|
| Information Extraction (IE) | 68.59% | 70.63% | 77.08% / 80.21% | 95.00% |
| Knowledge Update (KU) | 37.50% | 47.50% | 47.50% / 61.25% | 89.38% |
| Temporal Reasoning (TR) | 82.50% (+3.75) | 82.50% (+2.50) | 78.75% / 80.00% | 95.00% |
| Event Ordering (EO) | 9.68% (+1.17) | 43.17% (+6.92) | 8.51% / 36.25% | 100.00% |
| Contradiction Resolution (CR) | 85.94% (+6.25) | 92.50% (+7.50) | 79.69% / 85.00% | 78.13% |
| Abstention (ABS) | 61.25% | 67.50% | 73.75% / 85.00% | 98.75% |
| Multi-Session Reasoning (MSR) | 58.44% | 54.87% | 64.17% / 64.81% | 68.95% |
| Instruction Following (IF) | 69.38% | 71.88% | 71.25% / 76.88% | 96.25% |
| Preference Following (PF) | 91.88% (+0.63) | 85.00% | 91.25% / 87.71% | 100.00% |
| Summarization (SUM) | 77.46% | 90.46% (+12.27) | 79.94% / 78.19% | 99.38% |
| FULL 10-CAT MEAN (400/400) | 64.26% | 70.60% | 67.19% / 73.53% | 92.08% |
Published Mohammadta/BEAM (100K, n = 400) Leaderboard Context
| System | Model & Runtime Regime | Judge Protocol | 100K (n = 400) Score |
|---|---|---|---|
past.dev |
Proprietary Cloud (openai/gpt-5.6-luna) |
Self-judged (gpt-5.6-luna) |
92.08% |
Hindsight / Exabase M-1 |
Cloud Memory Services | BEAM Judge | 86.20% / 76.90% |
krusch-context-mcp (bge-large / arctic-embed2) |
Single-Box Air-Gapped Open-Weights (gpt-oss:120b, 8K budget) |
Cross-Family (hermes3 / qwen2.5:32b) |
73.53%–70.60% / 67.19%–64.26% |
Honcho / MEMIR (Jin et al., 2026) |
Cloud Memory / Academic Baseline | BEAM Judge | 63.00% / 48.26% |
Table C: In-Place 120B-SRE QLoRA Fusion Ablation (400/400)
Fusing our rank-16 BF16 SRE code-audit adapter (krush420/gpt-oss-120b-sre-lora) into gpt-oss:120b in 2.00s trades open-ended narrative verbosity (SUM -8.73 / -14.54 pp) for sharper state-mutation precision — pushing Contradiction Resolution to 98.13% (+20.00 pp above past.dev):
| BEAM Category (n = 40 each) | Stock 120B (32B) |
QLoRA 120B-SRE (32B) |
Δ (32B) |
Stock 120B (8B) |
QLoRA 120B-SRE (8B) |
Δ (8B) |
|---|---|---|---|---|---|---|
| Contradiction Resolution (CR) | 85.94% | 85.00% | -0.94 pp | 92.50% | 98.13% | +5.63 pp |
| Multi-Session Reasoning (MSR) | 58.44% | 57.69% | -0.75 pp | 54.87% | 62.87% | +8.00 pp |
| Knowledge Update (KU) | 37.50% | 38.75% | +1.25 pp | 47.50% | 52.50% | +5.00 pp |
| Preference Following (PF) | 91.88% | 90.63% | -1.25 pp | 85.00% | 89.38% | +4.38 pp |
| Information Extraction (IE) | 68.59% | 69.53% | +0.94 pp | 70.63% | 73.75% | +3.12 pp |
| Abstention / EO / IF / SUM / TR | 62.45% (mean) | 53.27% (mean) | -9.18 pp | 71.10% (mean) | 62.73% (mean) | -8.37 pp |
| FULL 10-CAT MEAN (n = 400/400) | 64.26% | 60.80% | -3.46 pp | 70.60% | 69.03% | -1.57 pp |
Why Stronger Embeddings Dipped 3 Categories on 100K (-2.93 pp)
- Semantic Neighbor Distractors on
Abstention(73.75%→61.25%): Unanswerable probes name real chat entities while asking about an unstated attribute; richer 8K neighborhoods tempt the Reader to hedge rather than refuse. - Passive Ingestion on
Knowledge Update(97.50%Recall →37.50%QA): Blind benchmark rules forbidsupersedelinks, packing both stale Turn #12 and updated Turn #148 side-by-side (whereas live IDE agents callkrusch_context_revise(action: "supersede")). - Exact-Count
Event OrderingRubrics (9.68%Qwen /43.17%Hermes): Rubrics demand "ONLY three [or five] macro-events"; listing 4 granular milestones scores0.0onqwen2.5:32b. ExcludingEOand passiveKU, Stock120Baverages74.43%/76.92%across the other 320 probes.
📈 7. Multi-Split Scaling: 500K, 1M & 10M (All 2,000/2,000 Probes on SQLite)
Without changing a byte of v1.9.0 retrieval code, we scaled across 500K (700 Qs), 1M (700 Qs), and BEAM-10M (200 Qs, 10,435 turns/chat) while keeping the Reader budget fixed at ~8K tokens:
| Official Split (~8K Budget) | Convs / Turns / Tokens | Conv Packed | Lex 8K | Dense 8K | Hybrid 8K (Δ vs Dense) | qwen2.5:32b | hermes3 | past.dev |
|---|---|---|---|---|---|---|---|---|
| 100K (400/400) | 20 / 2,866 / ~3.06M | 47.40% (67.9t) |
30.74% |
92.41% |
92.37% (-0.04 pp) |
64.26% |
70.60% |
92.08% |
| 500K (700/700) | 35 / 19,029 / ~19.40M | 12.67% (68.9t) |
6.55% |
78.81% |
81.51% (+2.70 pp) |
62.31% |
71.82% |
89.63% |
| 1M (700/700) | 35 / 37,315 / ~40.02M | 6.69% (71.3t) |
0.70% |
72.24% |
74.15% (+1.91 pp) |
64.64% |
72.86% |
90.65% |
| 10M (200/200) | 10 / 104,349 / ~115.87M | 0.66% (69.1t) |
0.00% |
53.51% |
54.78% (+1.27 pp) |
47.35% |
58.78% |
85.03% |
| Question-Weighted (2,000 Qs) | 100 / 163,559 / ~178.34M | ~69.6t / query | 8.71% |
76.88% |
78.67% (+1.79 pp) |
62.02% |
70.64% |
— |
| 4-Split Macro Mean | All 4 Splits | 16.86% |
9.50% |
74.24% |
75.70% (+1.46 pp) |
59.64% |
68.51% |
89.35% |
- Pure Dense Breaks Past
500K: Once an 8K window packs≤ 12.7%of history, hybrid scoring + PorterFTS5beats Pure Dense on every long split (+2.70 ppat500K,+1.91 ppat1M,+1.27 ppat10M;+23.00 ppon10MIE). - Zero Context Rot up to
1M: Scaling conversation length13×in tokens at fixed prompt cost produced zero E2E drop (70.60%→71.82%→72.86%onhermes3;Knowledge Updateactually rose+27.5 ppfrom100Kto10Mas top-K competition pushed stale early turns out of the window). - 4/4 Split Sweep on Contradiction Resolution: Deterministic conflict headers + Stock
gpt-oss:120bbeat cloudpast.devacross all four splits (92.50 / 89.64 / 77.68 / 78.75%vs.78.13 / 78.57 / 75.36 / 73.13%). - SQLite Was Never the Bottleneck: Node 22
node:sqlite+4 KBFloat32Arrayblobs scanned 100% of10,435-turn chats in< 300 MBRSS (152.3cold embeds/sec).
🚀 8. Multi-Scale Retrieval Upgrade: krusch-context-mcp v2.0.0
Targeting the 10M leaf-turn bottlenecks diagnosed above, krusch-context-mcp v2.0.0 (commit 694ff34, 124/124 tests) adds three zero-LLM, zero-RPC stages inside the unchanged 5-verb contract and ~8K budget:
- Two-Level Episode Rollups (
src/episode-rollup.js): Extractive 64-turn/session digests + salience-weightedFloat32Array(1024)centroids (O(1)SQLite watermark cache;stripTurnCitationsprevents leaf Turn-ID spoofing) emit macro timeline panoramas and pin standingUSER:directives. - Gated 2-Hop Residual Bridges (
src/retrieval-bridge.js): Orthogonal Gram-Schmidt residual vectors (vbridge = normalize(vhop1 − 0.75⟨vhop1, vq⟩vq)) + disjoint-sessionFTS5expansion rescue missing multi-session facets, rank-capped at0.84 / 0.76below Hop-1 Top-10 anchors. log10(N)Attribute Abstention (src/retrieval-epistemic.js): Checks±1-turnUSER:stem co-occurrence with corpus-scale cosine thresholds so10,000-turn entity distractors (0.48–0.59raw cosine) still trigger grounding warnings.
Table H: 4-Split Retrieval (v1.9.0 vs. Calibrated v2.0.0, All 2,000/2,000 Probes)
Split (~8K) |
Dense 8K | v1.9.0 R@10 / 20 / 30 / 50 |
v2.0.0 R@10 / 20 / 30 / 50 |
v1.9.0 8K |
v2.0.0 8K (Δ vs Dense) |
Notable Category Lifts |
|---|---|---|---|---|---|---|
100K (400) |
92.50% |
57.69 / 70.88 / 78.04 / 88.69% |
57.79 / 71.17 / 78.38 / 88.93% |
92.37% |
92.58% (+0.08 pp) |
IE 93.75% → 96.25%; EO 81.19%; SUM 75.20% |
500K (700) |
78.81% |
50.89 / 61.85 / 68.05 / 77.28% |
50.54 / 61.85 / 67.65 / 77.02% |
81.51% |
81.12% (+2.31 pp) |
SUM 46.06% → 47.49%; TR 97.86%; IF R@20 +1.43 pp |
1M (700) |
72.24% |
41.00 / 52.78 / 57.87 / 69.02% |
42.23 / 52.69 / 58.41 / 68.62% |
74.15% |
73.84% (+1.60 pp) |
R@10 +1.23 pp (IF R@10 +5.71 pp; TR R@10 +3.97 pp) |
10M (200) |
53.51% |
32.42 / 38.93 / 43.97 / 51.31% |
31.53 / 39.23 / 42.27 / 50.82% |
54.78% |
55.54% (+2.03 pp) |
IE 8K 88% → 93% (+28 pp vs Dense); IF +2.50 pp; CR +1.67 pp |
| Macro Mean | 74.27% |
45.50% (R@10) |
45.52% (R@10) |
75.70% |
75.77% (+1.50 pp) |
Beats Pure Dense 8K on all 4 splits |
Table I: Closed-System BEAM-10M Head-to-Head (v1.9.0 vs. v2.0.0, n = 200/200, 81.00% Judge Agreement)
| BEAM-10M Category (20/20 each) | v1.9.0 R@10 / 8K |
v2.0.0 R@10 / 8K |
v1.9.0 E2E (32B / 8B) |
v2.0.0 E2E (32B / 8B) |
Δ E2E (32B / 8B) |
past.dev |
|---|---|---|---|---|---|---|
| Information Extraction (IE) | 50.00 / 88.00% |
40.00 / 93.00% |
57.50 / 67.50% |
56.25% / 70.00% |
−1.25 / +2.50 pp (beats past.dev) |
68.75% |
| Knowledge Update (KU) | 73.33 / 83.75% |
74.58 / 83.75% |
65.00 / 70.00% |
57.50% / 70.00% |
−7.50 / 0.00 pp (R@10 +1.25 pp) |
92.50% |
| Temporal Reasoning (TR) | 35.74 / 49.69% |
36.20 / 49.69% |
27.50 / 47.50% |
30.00% / 37.50% |
+2.50 / −10.00 pp |
93.75% |
| Event Ordering (EO) | 7.19 / 23.63% |
6.36 / 22.58% |
7.50 / 30.00% |
10.57 / 39.88% |
+3.07 / +9.88 pp (Panorama) |
100.00% |
| Contradiction Resolution (CR) | 53.13 / 73.06% |
55.93 / 74.73% |
55.00 / 78.75% |
55.63% / 71.88% |
+0.63 / −6.87 pp (8K +1.67 pp) |
73.13% |
| Abstention (ABS) | — |
— |
45.00 / 60.00% |
55.00 / 55.00% |
+10.00 / −5.00 pp (log10(N)) |
100.00% |
| Multi-Session Reasoning (MSR) | 37.67 / 57.21% |
35.67 / 54.71% |
17.75 / 29.58% |
29.54 / 38.33% |
+11.79 / +8.75 pp (beats past.dev!) |
28.17% |
| Instruction Following (IF) | 5.00 / 48.75% |
5.00 / 51.25% |
71.25 / 66.25% |
67.50% / 83.75% |
−3.75 / +17.50 pp (Directive Pin) |
95.00% |
| Preference Following (PF) | 27.50 / 56.00% |
25.00 / 56.00% |
68.75 / 60.00% |
66.25 / 48.75% |
−2.50 / −11.25 pp |
100.00% |
| Summarization (SUM) | 2.26 / 12.93% |
5.07 / 14.18% |
58.21 / 78.25% |
53.58 / 72.00% |
−4.63 / −6.25 pp (8K +1.25 pp) |
99.00% |
10M OVERALL MEAN (200/200) |
32.42 / 54.78% |
31.53 / 55.54% |
47.35 / 58.78% |
48.18 / 58.71% |
+0.83 / −0.07 pp (+4.00 pp agree) |
85.03% |
v2.0.0 vs. v1.9.0:
- Rank-Capped 2-Hop Bridges Win Multi-Session QA: Capping Hop-2 rescues below Hop-1 Top-10 anchors (
0.84 / 0.76) lifted1MR@10(+1.23 pp) and10MMSR E2E by+11.79 pp/+8.75 pp— beating cloudpast.dev(28.17%) on both Referees. - Cosine Gates Need Corpus-Size Scaling: Across
10,435turns, extreme-value max cosine drifts upward by~0.10; scaling grounding thresholds bylog10(N)recovered+10.00 ppon10MAbstention while hitting93.00%IErecall. - Extractive vs. Abstractive Boundary: Zero-LLM extractive rollups boosted structural categories (
IF +17.50 pp,EO +9.88 pp) while slightly crowding raw turns on narrativeSUM(−4.6to−6.3 pp) — confirming that95%+10Msummarization requires write-time/closeLLM session handoffs.
🧪 9. Cryptographic Provenance & One-Command Reproduction
Every dataset shard, retrieval module, model weight digest, and 2,000/2,000 audit log (v1.9.0 and v2.0.0) is SHA-256 verified offline:
| Locked Artifact / Model | Path / Ollama Tag | Verified SHA-256 Digest |
|---|---|---|
| Official BEAM 100K / 500K / 1M / 10M | Mohammadta/BEAM + BEAM-10M |
d542da9e... · af05921c... · 41b5acbb... · 31d96fd4... |
| Embedding & Isotropic Calibration | src/embedding-helper.js |
7d60fc55d0b2fdb86f9bbd6832688682... |
v2.0.0 Multi-Scale Retrieval Stack |
src/{episode-rollup,retrieval-bridge,retrieval-epistemic,unified-retrieval}.js |
0dd35eb2... · e560c643... · dafb1885... · 36374f0a... |
| 100K & Long-Context Harnesses | scripts/benchmark_official_beam{,_long}.js |
1c6d70c3... · 2ce80a56... |
v1.9.0 100K (+ QLoRA) / 500K / 1M / 10M Logs |
benchmarks/beam_{100k,500k,1m,10m}_audit_log.json |
b01330af... (69f93d66...) · 19644d5f... · 20ce9281... · bc70c9f9... |
v2.0.0 Calibrated 100K / 500K / 1M / 10M Logs |
benchmarks/g4_closed_system_v200/beam_{100k,500k,1m,10m}_v200_audit_log.json |
f20825bd... · d99f8e13... · 421de391... · ac29b976... |
| Open-Weights Stack (4 Models) | arctic-embed2 · gpt-oss:120b · qwen2.5:32b · hermes3 |
5de93a84... · 714d8695... · 9f13ba12... · 4f6b83f3... |
# Clone krusch-context-mcp v2.0.0 and run all 124 SQLite unit + honesty tests (zero Docker)
git clone https://github.com/kruschdev/krusch-context-mcp.git
cd krusch-context-mcp && npm install && npm test

# Verify 5/5 zero-leakage checks, SHA-256 digests & 2,000/2,000 Dual-Judge tallies (v1.9.0 & v2.0.0)
npm run bench:beam:verify && npm run bench:beam:verify:long
node benchmarks/verify_zero_leakage.js --audit-log=benchmarks/g4_closed_system_v200/beam_100k_v200_audit_log.json
node benchmarks/verify_zero_leakage_long.js --split=500K --audit-log=benchmarks/g4_closed_system_v200/beam_500k_v200_audit_log.json
node benchmarks/verify_zero_leakage_long.js --split=1M --audit-log=benchmarks/g4_closed_system_v200/beam_1m_v200_audit_log.json
node benchmarks/verify_zero_leakage_long.js --split=10M --audit-log=benchmarks/g4_closed_system_v200/beam_10m_v200_audit_log.json

# Reproduce hermetic single-box runs on a 96GB Blackwell GPU
./scripts/run_beam_closed_g4.sh && ./scripts/run_beam_long_closed_g4.sh- GitHub (v2.0.0, 82★): github.com/kruschdev/krusch-context-mcp
- Archival Per-Split Tables & Verifiers: BEAM_EMPIRICAL_REPORT.md, verify_zero_leakage.js & verify_zero_leakage_long.js
- 120B SRE QLoRA Adapter: huggingface.co/krush420/gpt-oss-120b-sre-lora
- Architecture Deep Dive: What Makes krusch-context-mcp Special: The 5-Verb Discipline
